NVIDIA
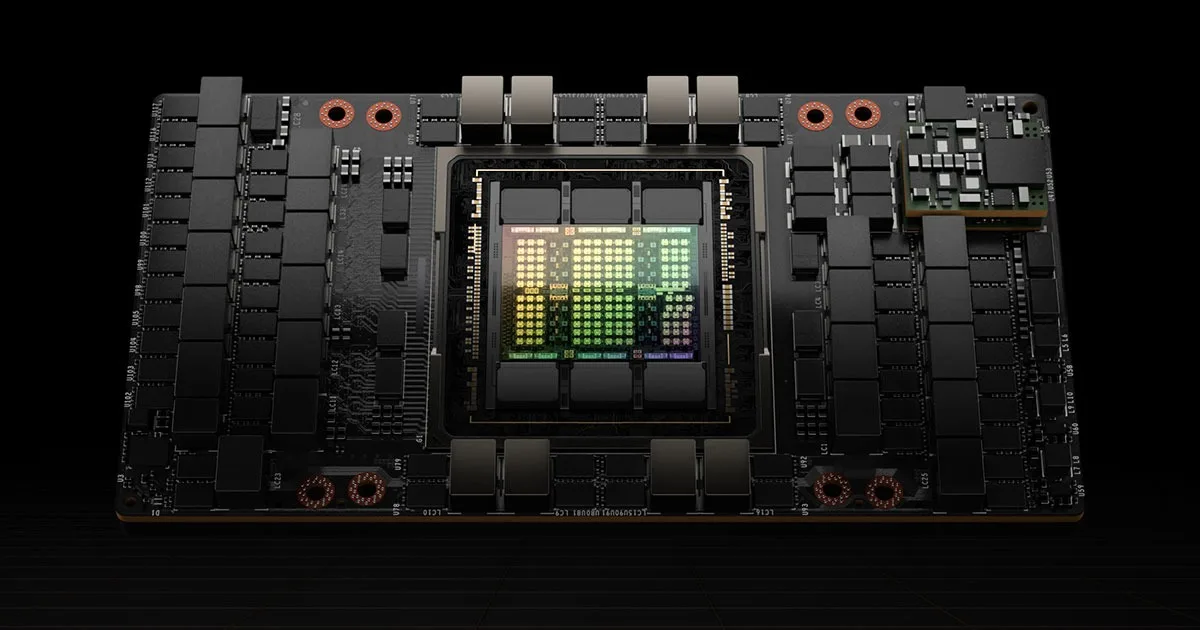
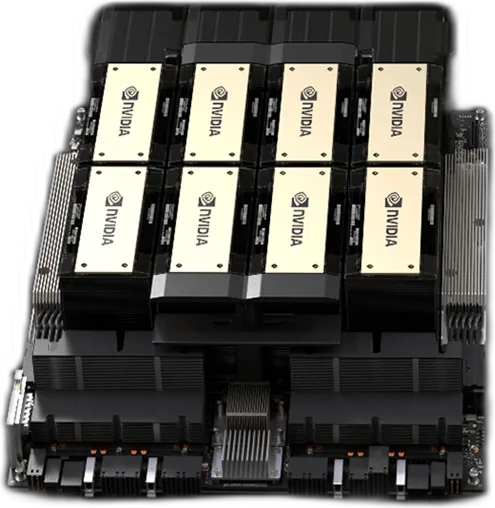
NVIDIA H200 (SXM)- Form factor: SXM (HGX)
- GPU memory: 141 GB HBM3e
- Architecture: NVIDIA Hopper
Pricing
On quote
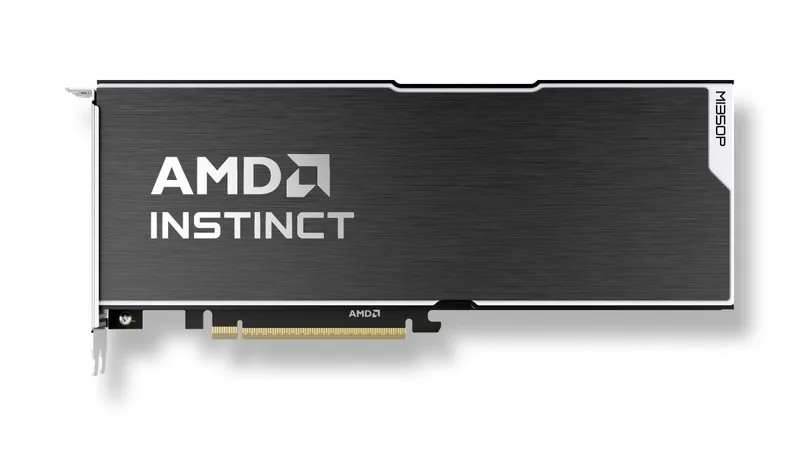
Product image for illustration; configuration may differ.
PCIe card with 144 GB HBM3E for running generative AI inside the servers you already have. Priced on quote.
| Board power | 600 W (450 W configurable) |
|---|---|
| Compute units | 128 (8,192 stream processors) |
| Peak FP16 / BF16 matrix | 1.15 PFLOPS |
| Peak FP8 (OCP) | 2.3 PFLOPS (4.6 with sparsity) |
| Memory bandwidth | Up to 4 TB/s |
| Power connector | 12V-2x6 |
| Peak MXFP4 / MXFP6 | 4.6 PFLOPS |
| Peak FP64 | 36 TFLOPS |
| Software | AMD ROCm (Linux x86-64) |
| Cooling | Passive (server airflow) |
| GPU memory | 144 GB HBM3E, 4096-bit |
| Form factor | PCIe 5.0 x16, full height, double slot, 267 mm |
| Architecture | AMD CDNA 4 |
AMD Instinct MI350P 144 GB PCIe is built to order and priced per project (configuration, delivery, installation and support).
Pick the model and quantisation you plan to run. We'll show whether it fits in memory, how much room is left for context, and the throughput to expect. Estimates come from memory bandwidth and are replaced by our own bench figures where we have them.
Machine
Quantisation
Comfortable. 70 GB spare — room for 128k context, a second small model, or a RAG index in memory. Expect roughly 3.8 tok/s single-stream.
Machines that run this configuration
Weights 42.8 GB at 4.85 bits/param · KV cache 5.0 GB at 16k (fp16, approximate) · 10 GB reserved for OS and runtime. Speed is single-stream decode, memory-bound; prompt processing and batching behave differently. Or WhatsApp an engineer on +44 7515 356 146.
The MI350P puts AMD's 4th-generation CDNA architecture on a standard double-slot PCIe card. With 144 GB of HBM3E on a 4096-bit interface and up to 4 TB/s of bandwidth, a single card holds models that would need two smaller GPUs, and the new MXFP4 and MXFP6 data types speed up inference further. Board power is 600 W, or 450 W where your rack's power or cooling budget is tighter.
It runs on AMD ROCm, the open software stack, with PyTorch, TensorFlow, JAX, Triton, SGLang and ONNX Runtime support and no per-GPU licence fees.
Fitted in a Workstation or Dell server, or supplied standalone where the form factor allows. Before it ships we check it against your chassis (power, airflow, slot layout and platform support), burn-in test it and install the AMD ROCm drivers and software stack. Warranty claims and advance replacements are handled by us, and support comes from our own UK engineers.
Priced on quote: tell us what you need and we will confirm price, availability and lead time.
Systems we build carry the warranty stated on your quote: three years return-to-base as standard. Parts carry their manufacturer's warranty, and we help you claim it.
Prices are shown ex VAT. VAT (20%) is added in your basket and on your quote. You can put your own purchase order number on a quote.
UK delivery is £35.00 ex VAT, shown before you pay. For high-value systems we may book a delivery slot or ask for a signature.
Business customers can return unopened stock items within 30 days of delivery (ask us for a returns number first). If you buy as a consumer, you can cancel within 14 days of receiving the goods. Faulty goods are always covered.