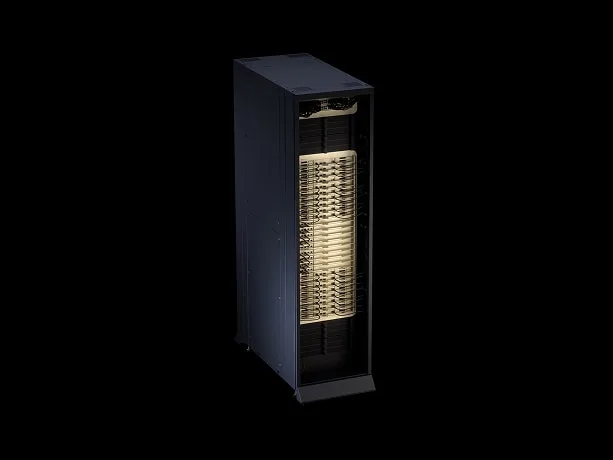
Product image for illustration; configuration may differ.
NVIDIA Vera Rubin NVL72 rack-scale system
Next-generation Vera Rubin NVL72 rack: 72 Rubin GPUs and 36 Vera CPUs, 20.7 TB of HBM4 in one NVLink 6 domain — priced on quote.
| AI performance | 3,600 PFLOPS NVFP4 inference, 2,520 PFLOPS NVFP4 training, 1,260 PFLOPS FP8 |
|---|---|
| NVLink | Sixth generation, 216 TB/s |
| Networking | ConnectX-9 SuperNICs, BlueField-4 DPUs, 32.4 TB/s |
| Cooling | Liquid cooled, 45°C inlet |
| GPU memory | 20.7 TB HBM4, 1,400 TB/s |
| GPUs | 72× NVIDIA Rubin |
| CPUs | 36× NVIDIA Vera (3,168 Olympus cores) |
| CPU memory | Up to 54 TB LPDDR5X |
NVIDIA Vera Rubin NVL72 rack-scale system is built to order and priced per project (configuration, delivery, installation and support).
Check a model against our machines before you buy.
Pick the model and quantisation you plan to run. We'll show whether it fits in memory, how much room is left for context, and the throughput to expect. Estimates come from memory bandwidth and are replaced by our own bench figures where we have them.
Machine
Quantisation
Comfortable. 70 GB spare — room for 128k context, a second small model, or a RAG index in memory. Expect roughly 3.8 tok/s single-stream.
Machines that run this configuration
Weights 42.8 GB at 4.85 bits/param · KV cache 5.0 GB at 16k (fp16, approximate) · 10 GB reserved for OS and runtime. Speed is single-stream decode, memory-bound; prompt processing and batching behave differently. Or WhatsApp an engineer on +44 7515 356 146.
NVIDIA's rack-scale system after Blackwell: 72 Rubin GPUs and 36 Vera CPUs, with ConnectX-9 SuperNICs and BlueField-4 DPUs, joined by sixth-generation NVLink into one 72-GPU domain. It is built for agentic AI, trillion-parameter models and million-token contexts. NVIDIA quotes about a tenth of the cost per million tokens and a quarter of the GPUs for mixture-of-experts training compared with GB200 NVL72. It uses the third-generation MGX NVL72 rack design, so sites already planned for GB200 or GB300 NVL72 have a clear upgrade path. It is liquid cooled, with an inlet temperature of up to 45°C.
Workstation runs this as a project: site survey, power and cooling design, rack layout, installation and cabling, then onboarding onto Base Command Manager or Mission Control, Kubernetes or Slurm. Ongoing monitoring and managed support contracts are available. Support comes from our own UK engineers, and Trade members get free tech support on every order.
Priced on quote: tell us what you need and we will confirm price, allocation and lead time with our suppliers.